vLLM Engineering:
End-to-End.
An eight-lecture live course on serving large language models with vLLM, taught by Dr. Sreedath Panat (MIT PhD). You read the engine, benchmark it, tune it, quantize and scale it, and finish with a production endpoint you deployed yourself.
Every session is recorded. Recordings included.
What vLLM does every step
Requests arrive, the scheduler admits them, one decode step advances every sequence in the batch, and each sequence's KV cache lives in blocks that are handed out and returned as it runs. This is the loop the whole course is about.
The engine that treats the KV cache like virtual memory
vLLM started in 2023 at UC Berkeley, when Woosuk Kwon, Zhuohan Li and their collaborators asked why LLM serving wasted so much GPU memory. Their answer, PagedAttention, manages the key-value cache the way an operating system manages memory: in fixed blocks, allocated on demand, shared where two requests overlap. Continuous batching sits on top of it, so a GPU is never idle waiting for the slowest request in a batch.
The project outgrew the paper. It became a community effort with thousands of contributors, joined the PyTorch Foundation in 2025, and rewrote its core as the V1 engine the same year. That engine, as it ships today, is what this course reads, benchmarks and deploys.
Efficient Memory Management for Large Language Model Serving with PagedAttention
Kwon, Li, Zhuang, Sheng, Zheng, Yu, Gonzalez, Zhang, Stoica
ReadvLLM V1: A Major Upgrade to vLLM's Core Architecture
The vLLM team
ReadWhy vLLM is worth learning properly
Three reasons, in short.
It is the engine you will meet
vLLM is the most widely used open-source inference engine, with over 92,000 GitHub stars and millions of downloads a month. If you serve open-weight models, it is either your engine or the one you are compared against.
The knobs decide the GPU bill
The same model on the same GPU can differ several times over in throughput depending on scheduler budgets, cache settings, quantization and parallelism. This course teaches you to measure each one instead of copying a config.
The ideas transfer
PagedAttention, continuous batching, prefix caching, and speculative decoding appear in SGLang, TensorRT-LLM and every serious serving stack. You learn them in the codebase where most of them were built.
The most used open-source inference engine
Four numbers from the public record, and how much the project ships each year.
Merged pull requests per year
How fast the codebase moves, and why reading it is a skill
Source: GitHub search, vllm-project/vllm, counted 22 September 2026.
What vLLM changes about serving
A plain generate loop pads a batch, preallocates the cache, and waits. vLLM schedules at the token level and manages the cache in blocks. The table shows what that changes, and what it hands you to tune.
The request path you trace in lecture 1
Each block is highlighted in turn with a note on what it does and which lecture goes deep on it.
API server
The OpenAI-compatible frontend. It validates the request, applies the chat template, tokenizes, and streams tokens back as they are produced. Structured outputs and tool-call parsers live here.
Three components you will read, measure and tune
Simplified views of three vLLM components. The ideas behind them are assumed knowledge. The lectures are about how vLLM implements each one, where it lives in the code, and which settings change the numbers.
The KV cache manager
vLLM's block pool and block tables. Each request's cache is a list of blocks, prefix hashes let matching prompts share blocks, and gpu_memory_utilization decides how many blocks exist at all.
The scheduler's step
How vLLM fills each step within max_num_seqs and max_num_batched_tokens. Finished requests leave, waiting ones join at the next step, and chunked prefill keeps long prompts from stalling decode.
Speculative decoding in vLLM
vLLM's drafter (EAGLE, MTP, n-gram or a draft model) proposes, the target verifies in one pass, and the rejection sampler keeps the accepted prefix. The acceptance rate is a metric you read off the server and decide with.
Eight lectures over four weeks
Two lectures a week. Every live hour is spent inside vLLM. Details may change as the material is finalized.
Inside the engine
vLLM architecture and the request lifecycle
What problem vLLM solves, the V1 engine (frontend, EngineCore, scheduler, KV cache manager, model runner, workers), PagedAttention, and how vLLM implements continuous batching and chunked prefill.
Build vLLM from source, trace one request through the code with logging, and run your first model.
Building an LLM server with vLLM
vllm serve and the OpenAI-compatible API, chat, completions and streaming, sampling parameters, structured outputs, tool-call and reasoning parsers, multi-LoRA serving, multimodal models, and serving Hugging Face checkpoints.
Deploy a server with several LoRA adapters and constrained JSON output, then build a small application on top of it.
Measure, then tune
Benchmarking vLLM
TTFT, TPOT, inter-token latency and throughput, request throughput versus token throughput, vllm bench and the benchmark suite, concurrency and load testing, GPU utilization and memory measurement, profiling with torch profiler and Nsight.
Design and run a benchmarking experiment whose numbers you can defend, and keep it as the harness for the rest of the course.
vLLM performance engineering
max_num_seqs, max_num_batched_tokens, gpu_memory_utilization, max_model_len, chunked prefill tuning, automatic prefix caching (hashing, eviction, hit rate), KV cache tuning, attention backends (FlashAttention, FlashInfer, Triton), CUDA graphs and torch.compile.
Tune a deployment against a latency target step by step, measuring every knob against the lecture 3 harness.
Fit more, run faster
Quantization and memory engineering in vLLM
Which formats vLLM supports on which hardware, the kernels behind them (Marlin, Machete, FP8 paths), producing a checkpoint vLLM loads with llm-compressor, KV cache precision, memory calculations, context length versus concurrency.
Quantize a model to FP8 and INT4, serve both, and compare accuracy, memory and latency with the BF16 baseline.
Multi-GPU and distributed vLLM
How vLLM implements tensor, pipeline, data and expert parallelism, MoE serving and MoE kernels, multi-node inference with Ray, and how to measure communication overhead.
Serve a large model across 1, 2, 4 and 8 GPUs, compare parallelism plans, and explain where the scaling stops.
Advanced and production
Speculative decoding, disaggregation, and extending vLLM
Speculative decoding in vLLM (EAGLE, MTP, n-gram, draft models, acceptance rate), disaggregated prefill and decode with KV connectors (LMCache, NIXL), when these techniques actually pay off, and how to add a model, a plugin, or a custom op to vLLM.
Add speculative decoding to your deployment, measure acceptance rate and speedup on a chat workload, and make a small change to the vLLM codebase.
Production vLLM and capstone
Dockerizing vLLM, Kubernetes and replicas, load balancing with prefix-aware routing, autoscaling, Prometheus metrics and observability, failure handling, cost per token and capacity planning.
Capstone: design, deploy, benchmark and optimize a production LLM endpoint, and present the numbers.
What you have built by the end
Everything lives in one repository that grows across the lectures. The benchmark harness from lecture 3 measures every change you make after it, up to the capstone endpoint.
A benchmark harness you trust
TTFT, TPOT, and throughput under load, built in lecture 3 and run against every change you make afterwards.
A tuned single-GPU deployment
Scheduler budgets, memory fraction, prefix caching, and the attention backend chosen from your own measurements, not from a blog post.
A quantized model in production form
An FP8 or INT4 checkpoint you produced with llm-compressor, served by vLLM, with the accuracy and latency difference documented.
A multi-GPU production endpoint
Served across GPUs, containerized, on Kubernetes with metrics and autoscaling, with a cost per million tokens you can defend.
The stack you work in, as it is used in production
Nothing here is a teaching substitute. These are the tools the labs run on.
vLLM
The engine, V1
FlashAttention / FlashInfer
Attention backends
llm-compressor
FP8 and INT4 checkpoints
xgrammar
Structured outputs
Ray
Multi-node serving
LMCache / NIXL
KV transfer
Docker + Kubernetes
Deployment
Prometheus + Grafana
Metrics
torch profiler + Nsight
Profiling
Ship an endpoint and defend the numbers
The last lecture is the capstone. You bring a deployment, its benchmark report, and the reasoning behind every setting.
A production LLM endpoint, with the numbers to prove it
Pick an open-weight model and a latency target, and take it to a running endpoint. You choose the hardware, tune the scheduler and cache, decide whether quantization and speculative decoding pay off, split the model across GPUs if it needs it, and ship it with metrics and autoscaling.
- A written service level target: p50 and p99 latency, throughput, and cost per million tokens
- A benchmark report that compares the baseline with every optimization you applied
- A Kubernetes deployment with Prometheus metrics and an autoscaling policy
- A short presentation of what you tried, what helped, and what did not
Who this course is for
- →Engineers who serve open-weight models and want to stop guessing which flags matter
- →ML engineers moving from training into inference and deployment
- →Platform and infrastructure engineers who own the GPU bill
- →Anyone who has learned inference fundamentals and wants to see those ideas inside a real engine
What you will be able to do
- →Explain how a request moves through vLLM and where the time goes
- →Benchmark a deployment properly and tune it to a latency or throughput target
- →Quantize a model, serve it, and measure what changed
- →Scale to multiple GPUs and choose the right parallelism plan
- →Deploy vLLM on Kubernetes with metrics, autoscaling, and a cost model
You should be comfortable with Python and the command line and have run a model on a GPU before. Labs run on rented cloud GPUs; a budget guide is shared before the cohort starts.
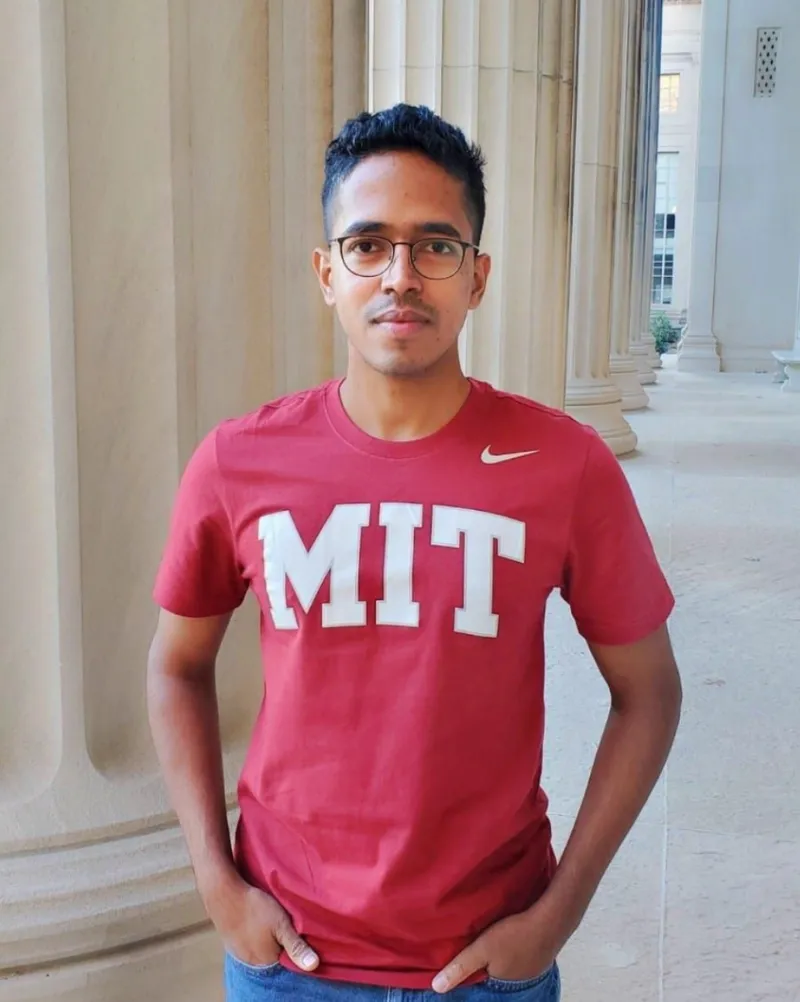
Dr. Sreedath Panat
MIT PhD · Vizuara AI Labs
Taught by Dr. Sreedath Panat
Dr. Sreedath holds a PhD from MIT and is the co-founder and director of Vizuara AI Labs. An IIT Madras graduate and department gold medalist, he has built a 200K+ subscriber YouTube channel and co-authored a Manning book on building DeepSeek from scratch. He teaches every concept from first principles.
- All 8 lectures personally delivered
- PhD from MIT
- IIT Madras graduate and department gold medalist
- Winner of the Langmuir Award
- 200K+ YouTube subscribers, 115K+ LinkedIn followers
Build a DeepSeek Model from Scratch
Raj Dandekar, Rajat Dandekar, Sreedath Panat, Naman Dwivedi
View on manning.comQuestions? Write to sreedath@vizuara.com
Start your research with a head start.
Do not start from scratch. Tell us your topic of interest and we will generate a personalised research roadmap and an initial version of your research paper, delivered asynchronously, so you can hit the ground running from day one.
What is in the kit
Personalised research roadmap (PDF)
You tell us your topic. We produce an 8-week plan with milestones, deliverables, and acceptance criteria for your inference or serving-systems research area: literature scope, experiment matrix, benchmark design, and manuscript timeline.
Initial research paper draft
A 6 to 8 page scaffold with the research questions framed, the method outlined, related work surveyed, and the experiment setup defined, so you never start from a blank page.
Curated paper reading list
12 to 15 papers chosen for your topic, with a reading order, key takeaways, and the connections between them, plus a literature matrix template.
Starter code template
A clean, documented codebase for an inference-systems research project: model loading, a vLLM serving harness, benchmark and trace collection, evaluation, and experiment config. Ready to run on day one.
Example research topics
Your roadmap is personalised to your background and goals. These are the kinds of topics the kit is built for.
Scheduling policies for mixed prefill and decode workloads
KV cache compression, quantization, and eviction strategies
Speculative decoding drafters for domain-specific models
Disaggregated prefill and decode across heterogeneous GPUs
Quantization accuracy versus latency on small and mid-sized models
Prefix-aware routing for multi-replica serving
Serving mixture-of-experts models with expert parallelism on few GPUs
Energy and cost per token measurement for open-weight models
Build your workshop
Select what you need. Everything adjusts instantly.
Step 1: choose your program
Step 2: or pick a bundle and save
Select a program to get started.
EMI available at checkout. All sales are final.
Learn vLLM from the source code to a production endpoint.
Eight live lectures, a benchmark harness and deployment you build yourself, and recordings you keep.
Cohort dates announced soon · Two lectures a week, 2 hours each, for four weeks